

Agentic AI
,
Artificial Intelligence & Machine Learning
,
Next-Generation Technologies & Secure Development
Combining Proven Security Principles With Modern Tooling to Improve Resilience
“A CISO, a CTO and a CLO walk into a bar. The barman asks what they want.”
See Also: Why Healthcare Leaders Are Rethinking Their Data Strategy Before Scaling AI
“Something proprietary,” the CLO says.
“Something open source,” the CTO says.
The CISO orders water and says, “Whatever you two pick, I’m the one writing the incident response plan.”
The joke captures the real dilemma facing technology leaders in 2026: someone owns the risk of every artificial intelligence decision, and it usually isn’t the person who made it.
The enterprise rush to adopt generative AI has created a paradox. On one hand, the productivity gains are undeniable – code generation, threat analysis and automation are being transformed by large language models. On the other hand, proprietary closed models introduce opaque data handling practices, vendor lock-in and the ever-present risk of sensitive prompts being retained for model training. For technology leaders navigating this landscape, open-weight and open-source models offer a compelling alternative.
Open-weight models deliver a combination of transparency, cost efficiency and data sovereignty. Unlike black-box proprietary services, they allow organizations to inspect model architecture and run inference entirely within their own infrastructure, thus eliminating the risk of sensitive data exfiltration to third-party APIs while avoiding vendor lock-in and unpredictable licensing costs. What they generally do not let you verify is training-data provenance: Open weights are not open data, so claims about what a model was trained on cannot be independently confirmed.
Open-source models go a step further, publishing data and code for reproducibility. Your organization needs to understand whether it is considering an open-weight or open-source model for business, security or compliance reasons. That difference shapes what you can verify.
The Security Imperative
The transition to open models is not without risk. When organizations self-host or fine-tune these models, they assume responsibility for the entire security stack – from infrastructure hardening to output validation. The attack surface expands across multiple vectors: Prompt injection attacks can manipulate model behavior to bypass safeguards, training data poisoning can embed backdoors that persist through fine-tuning and insecure model registries can introduce supply chain compromises.
For tech leaders, the challenge is not whether to adopt open models, but how to do so without compromising the organization’s security posture.
Approach to Secure Open-Model Deployment
Security leaders should adopt a defense-in-depth strategy that mirrors zero-trust principles.
First, establish model provenance discipline. Every open-weight model deployed in production should have a verifiable chain of custody for the artifact itself – from the origin repository through any fine-tuning or quantization steps and cryptographic signing, for example, Sigstore-style model signing, so tampering can be detected. Implement an AI bill of materials to track model dependencies, base images and known vulnerabilities. The National Institute of Standards and Technology AI Risk Management Framework provides a structured governance methodology.
Second, implement strict network and runtime isolation. Open models should execute within containerized environments with minimal privileges, segregated from production networks and sensitive data stores. Use read-only filesystems, disable unnecessary network egress and enforce resource limits to prevent denial-of-service conditions. For organizations not ready to self-host, proxy architectures with strict zero-data-retention policies can provide an intermediate layer of control. ZDR is a guarantee you extract from a third party. But, when you self-host, the equivalent control is disabling prompt logging and ensuring observability agents never capture request bodies.
Third, treat all model outputs as potentially malicious. Implement output validation pipelines that scan generated code for known vulnerabilities, malicious patterns and insecure dependencies. For security-critical applications, enforce human-in-the-loop review before any AI-generated output reaches production systems. This is particularly crucial when models are used for code generation, configuration management or automated remediation workflows.
Self-Hosting Quantized Models on Cloud GPU Clusters
One of the options now available to enterprises is self-hosting quantized open-weight models on dedicated cloud GPU clusters. Quantization reduces model precision from FP16 or FP32 down to INT8 or INT4, slashing memory requirements and inference latency.
Be realistic about hardware. Quantization makes mid-sized open-weight models – roughly the 20 to 70 billion parameters – genuinely viable on modest single or dual-GPU instances. Frontier open-weight models are a different story. Z.ai’s GLM-5.2 needs around 400 GB of memory even at 4-bit, and Moonshot AI’s Kimi K3 – having 2.8 trillion parameters – is larger still. For these, plan for multi-GPU and often multi-node serving and large budgets.
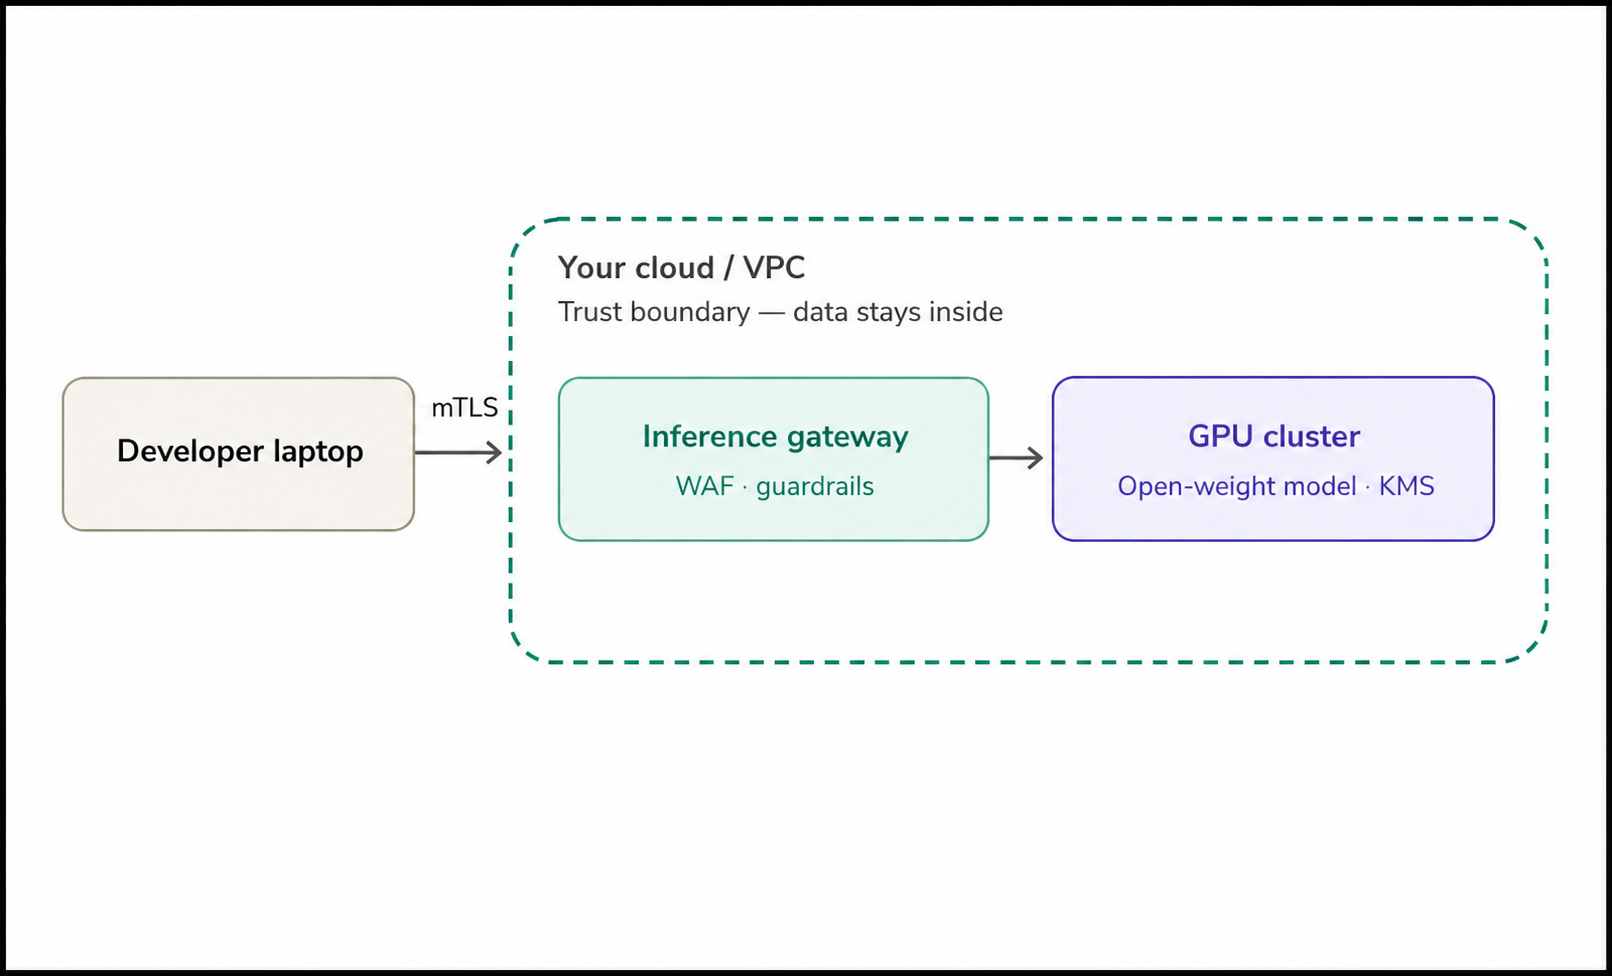
Running these models on cloud infrastructure introduces a distinct set of security responsibilities. The model weights should be encrypted at rest. Access to the GPU cluster should be gated through identity-aware proxies and short-lived credentials rather than long-lived API keys. Network policies must restrict the inference service to approved client subnets, with all inter-service communication encrypted via mutual TLS.
Container hardening is nonnegotiable. If using Kubernetes, deploy models within dedicated namespaces with network policies that deny all egress except to essential endpoints.
Regularly scan base images for CVEs, and pin image digests rather than relying on mutable tags. Deploy a web application firewall in front of the inference endpoint, enforce rate limiting, and log all requests for anomaly detection, redacting prompt and response bodies so that security logging does not become a data-leak vector.
Points for Action
- Conduct a model risk assessment before deployment: Catalog all open-weight models in use, identify their origin and license terms, and evaluate them against your organization’s risk appetite.
- Scrutinize model origin and licensing: Licenses range from permissive to modified terms with usage caps or acceptable-use clauses. Origin matters too: Models from jurisdictions subject to export controls or procurement restrictions may be unsuitable for certain clients or regulated workloads regardless of technical merit.
- Implement prompt injection defenses: Deploy input sanitization, context boundary enforcement and output filtering. Use structured output schemas to constrain responses.
- Enforce disciplined data retention: Whether self-hosting or using third-party inference providers, ensure prompts, responses and metadata are handled per policy. Demand contractual ZDR from third parties.
- Harden the GPU cluster infrastructure: Apply the container controls above, encrypt weights at rest and segment the inference network from general corporate traffic.
- Govern fine-tuning data: Anything you fine-tune becomes embedded in the weights, which are both IP and a potential exfiltration channel via membership-inference and extraction attacks. Apply the same data classification and minimization to fine-tune corpora as to production databases.
- Train development teams on AI-specific secure coding practices: Developers must understand direct and indirect prompt injection, the risks of over-reliance on AI-generated code, and your organization’s sanctioned-tool policy.
Recommended Tools and Platforms
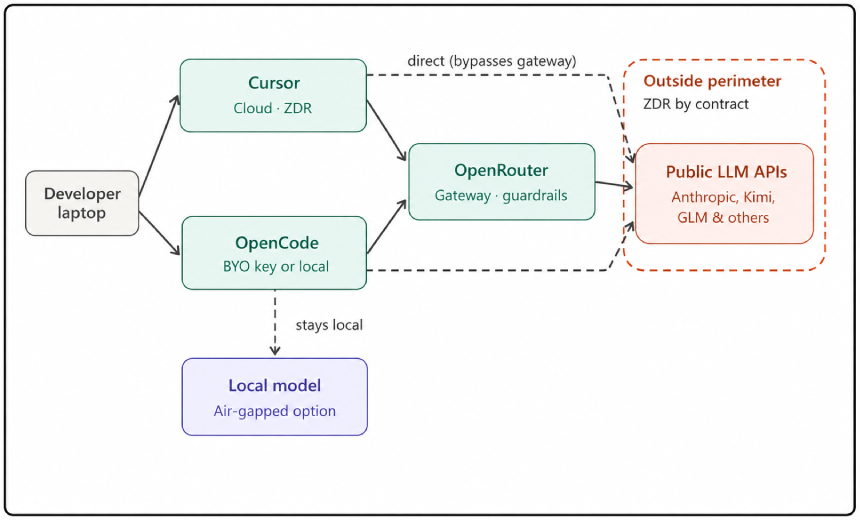
Securing open-model deployments and equipping developers who use AI are related but distinct problems. The three platforms shared below address the developer surface. They are complementary to the deployment hardening above, not a substitute for it, and two of them route to proprietary third-party APIs, which sits in tension with the data-sovereignty argument for open models. Weigh that trade-off explicitly.
For securing self-hosted deployments, evaluate model-scanning tools such as Protect AI’s ModelScan/Guardian to catch unsafe serialized weights; adversarial red-teaming frameworks such as garak; guardrail layers such as Llama Guard, NeMo Guardrails or Meta’s LlamaFirewall for input/output filtering; vLLM for hardened high-throughput serving; and Sigstore-based signing for weight integrity.
For securing access to public models, you can consider:
- Cursor is a leading AI-native code editor with enterprise controls. On its business and enterprise tiers, it maintains ZDR agreements with its model providers and is SOC 2 Type II-certified with regular penetration testing. For teams that can accept a cloud-only model, it is a pragmatic balance of productivity and control.
- OpenCode is an open-source, terminal-native AI coding agent for organizations that prioritize transparency and self-sovereignty. It is bring-your-own-key, self-hostable and can run entirely against local models via Ollama. Note that with cloud provider keys, code still transits to that provider. Security teams can audit and fork the client to enforce organizational policy, which suits highly regulated environments willing to invest the operational effort.
- OpenRouter provides a unified gateway across many model providers with a guardrails layer: It scans requests against OWASP-derived prompt-injection patterns and detects PII/sensitive data with redact-or-block enforcement before traffic leaves the gateway, along with rate limiting and audit logging capabilities. For multi-model strategies, it standardizes controls across providers.
What Else to Consider
- Red teaming should be institutionalized as a continuous practice, with automated adversarial testing probing for jailbreaks and data-extraction risks;
- Regulatory alignment is a live dimension, and self-hosting can change your legal posture. Under the EU AI Act, an organization that fine-tunes or substantially modifies a general-purpose AI model may itself take on “provider” obligations. Risk-based classification will directly shape how open models can be deployed for high-risk uses such as automated decision-making in security operations;
- Finally, consider the human element. Establish clear acceptable-use policies, provide sanctioned alternatives that meet security requirements and create feedback channels so teams can request new capabilities without resorting to shadow AI.
Conclusion
Open-weight and open-source models represent a strategic inflection point for enterprise AI adoption. They offer the transparency and control security leaders have long demanded, but they transfer operational responsibility and liability to the organization. By combining proven security principles with modern tooling and by being honest about where “open” shifts risk onto you, technology leaders can harness the innovation of open AI without compromising their security posture.